Best Source International ltd.,
Key Features & Advantages:
NVIDIA Hopper Architecture & Transformer Engine: Automatically adjusts precision between FP8 and FP16 formats, drastically accelerating transformer model training and inference speed without sacrificing accuracy.
4th-Generation NVLink: Provides up to 900 GB/s bidirectional bandwidth per GPU, enabling seamless multi-GPU scaling across server clusters to tackle the most demanding enterprise workloads.
Confidential Computing: Protects the integrity and confidentiality of your AI models and data against unauthorized access at the hardware level, ensuring enterprise-grade security.
Unmatched Efficiency for Generative AI: Delivers up to 30x faster inference and up to 9x faster training performance compared to previous generations, making it the ultimate hardware choice for generative AI deployments.
Typical Applications:
Large Language Model (LLM) Training and Fine-tuning
Generative AI & Natural Language Processing (NLP)
Computer Vision and Deep Learning Research
High-Performance Computing (HPC) & Scientific Simulations
Enterprise Data Center Deployments
Highly customized tea processing machine to meet your special needs, strictly product quality control is our requirement .
High-Performance Compute & AI Accelerator for Enterprise Data Centers
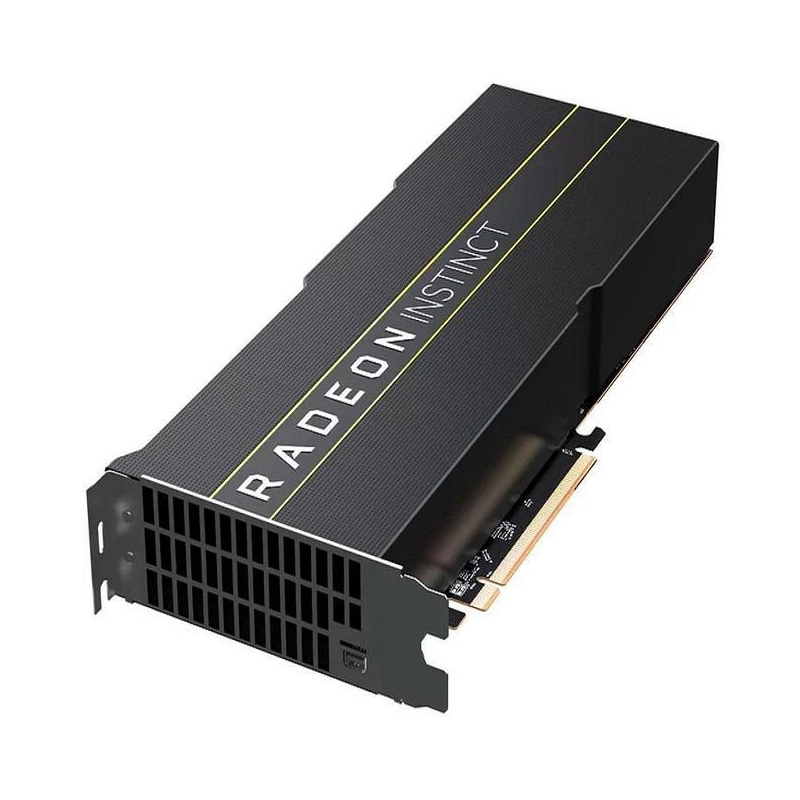
The AMD Radeon Instinct MI50 is an enterprise-grade GPU accelerator engineered for high-performance computing (HPC), deep learning inference, and data analytics. Built on advanced 7nm process technology and featuring ultra-fast HBM2 memory with up to 1.0 TB/s bandwidth, the MI50 delivers exceptional compute density and energy efficiency for modern server infrastructures.
Powered by the open-source AMD ROCm™ software platform and featuring AMD Infinity Fabric™ Link interconnects, the Radeon Instinct MI50 provides scalable compute power and seamless multi-GPU communication for enterprise data centers and scientific research applications.
Next-Generation Professional & Server Graphics Card for Enterprise AI and Visualization
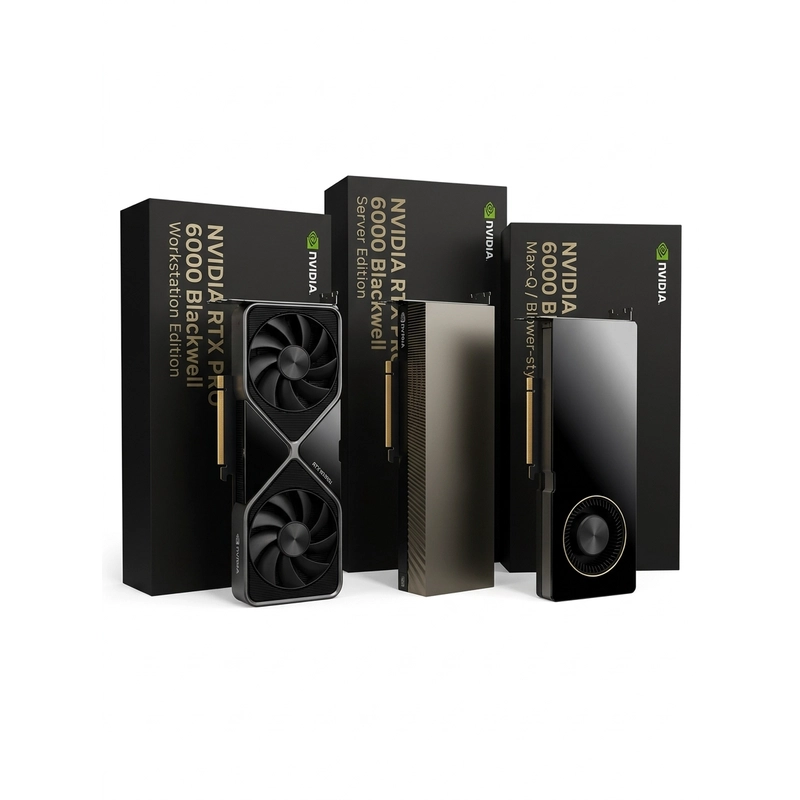
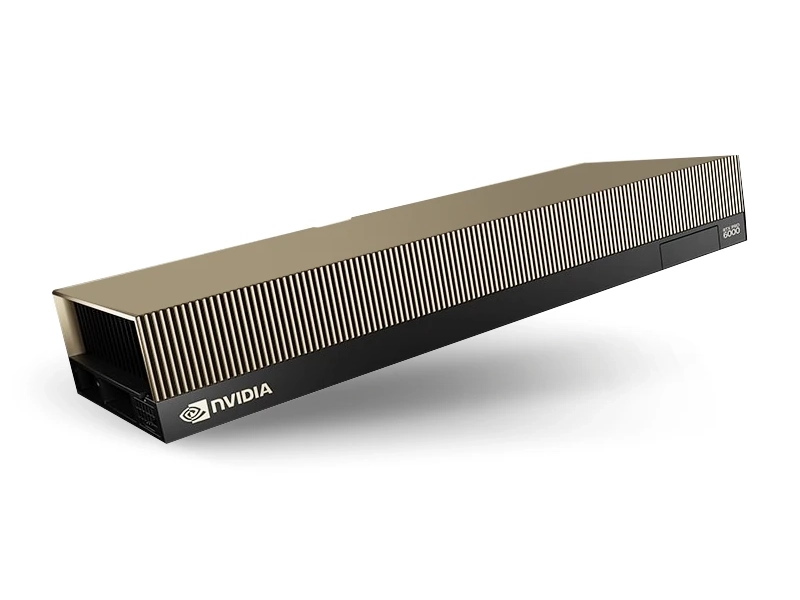
As the official successor to the acclaimed RTX 6000 Ada, the NVIDIA RTX PRO 6000 Blackwell and RTX 6000 Blackwell Server Edition set a new benchmark for enterprise computing. Built on the revolutionary Blackwell architecture, this professional GPU delivers massive performance leaps in generative AI, real-time 3D ray tracing, complex physical simulations, and server-side virtual workstation deployments.
Designed to operate in demanding enterprise environments, this high-density server graphics card combines workstation precision with data center reliability, making it the ideal foundation for enterprise AI pipelines, LLM fine-tuning, and cloud rendering infrastructure.
Unrivaled Performance for AI Supercomputing and Extreme Gaming
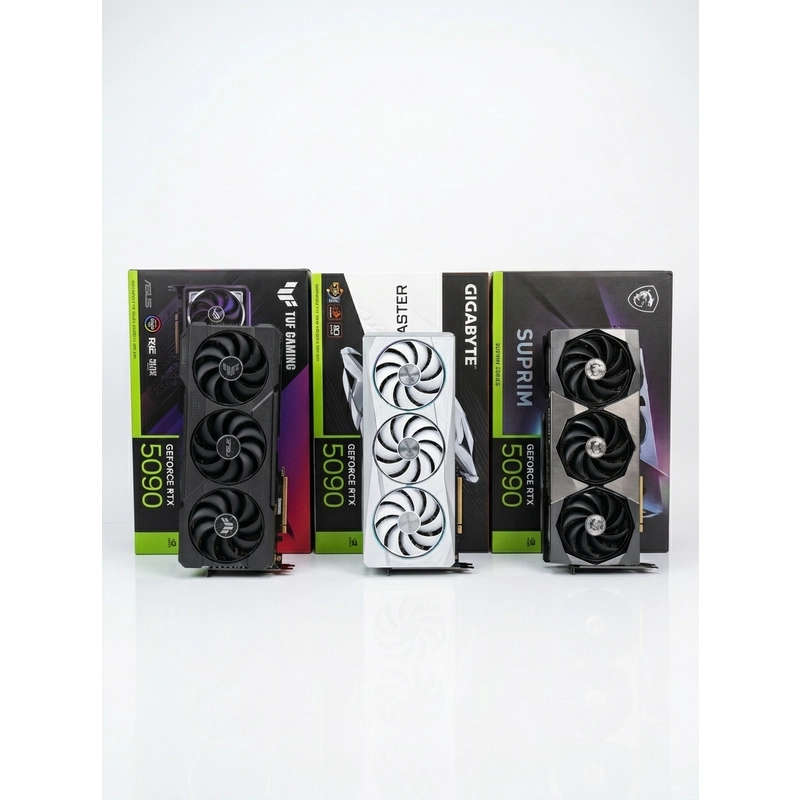
Dominate the frontier of artificial intelligence and graphics with the NVIDIA GeForce RTX 5090. Built on NVIDIA’s latest Blackwell architecture and equipped with advanced high-bandwidth memory (HBM3/GDDR7) alongside the Transformer Engine, the RTX 5090 delivers unprecedented compute density for enterprise AI development and enthusiast desktop builds.
Featuring high-speed PCIe Gen5 connectivity and ultra-fast NVLink 900 GB/s interconnect support, the GeForce RTX 5090 seamlessly bridges the gap between ultra-heavy AI supercomputing workloads and raw, uncompromised 4K/8K real-time ray tracing performance.
Unmatched 4K Gaming and AI Performance with Next-Gen Blackwell Architecture
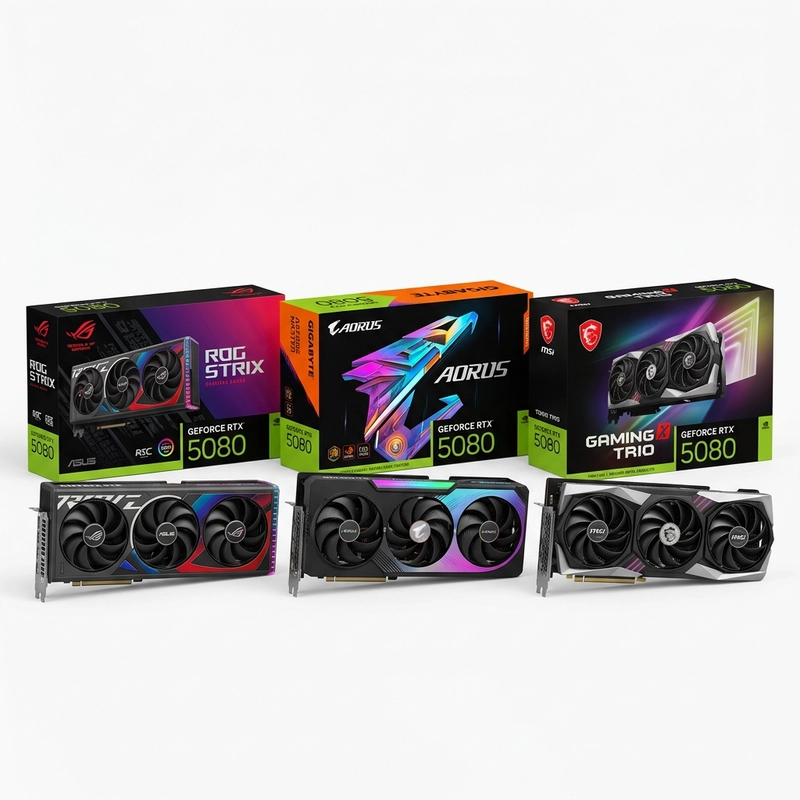
Push the boundaries of visual fidelity with the GeForce RTX 5080, NVIDIA’s premier high-end PC GPU engineered for enthusiast NVIDIA builders and hardcore gamers. Powered by the groundbreaking Blackwell GPU architecture and ultra-fast GDDR7 memory, the RTX 5080 delivers incredible frame rates, low latency, and realistic ray-traced graphics.
Designed as the ultimate 4K gaming graphics card, the RTX 5080 leverages advanced DLSS technology and 5th Generation Tensor Cores to accelerate high-resolution gaming, 8K video rendering, and heavy local AI inference workloads effortlessly.
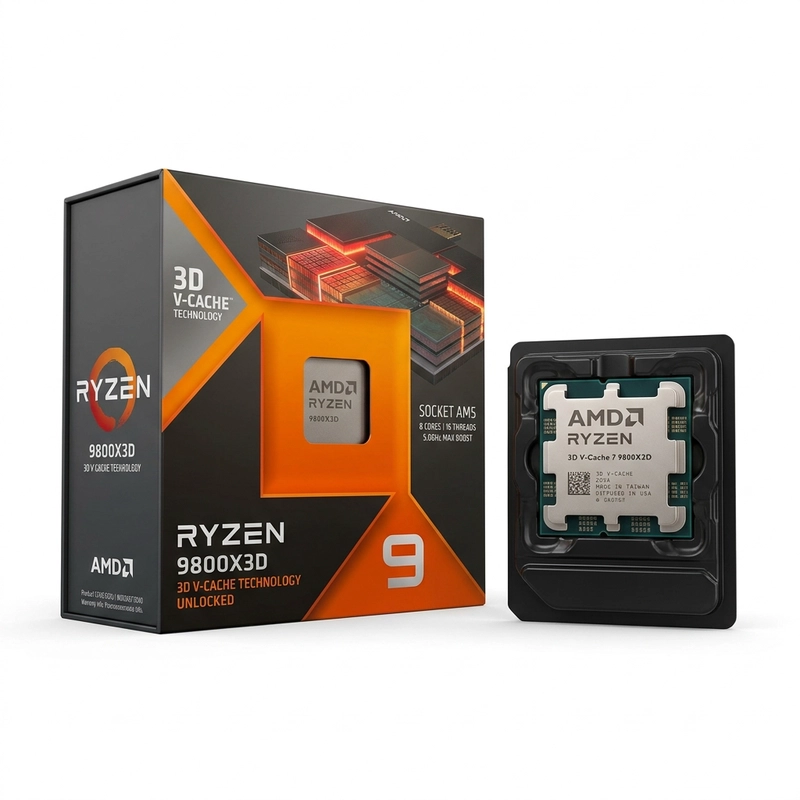
The World's Fastest Gaming Processor Built on Zen 5 Architecture
Dominate competitive gaming and high-frame-rate Esports titles with the AMD Ryzen 7 9800X3D, available in both retail Boxed and cost-effective OEM Tray configurations. Engineered with AMD’s revolutionary 2nd-generation 3D V-Cache™ technology, the cache stack is positioned below the CCD, enabling higher clock speeds and superior thermal dissipation for unmatched gaming performance.
Whether you select the retail Boxed edition or the Tray / Bulk version tailored for custom liquid-cooled rigs and system integration, the Ryzen 7 9800X3D delivers smooth 1% low frame rates, low latency, and full overclocking support on Socket AM5 platforms.
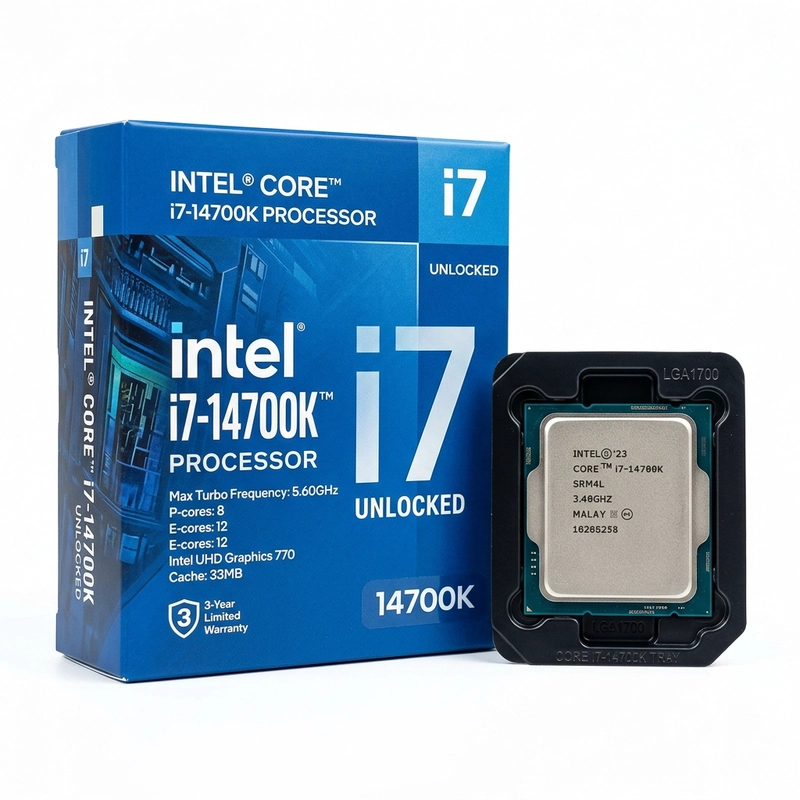
Extreme Performance with 20-Core Architecture for Enthusiasts and System Builders
Power up your desktop infrastructure with the Intel Core i7-14700K, available in both retail Boxed and cost-effective OEM Tray / Bulk packaging. Featuring a upgraded hybrid architecture with 20 cores (8 P-cores + 12 E-cores) and 28 threads, the i7-14700K delivers massive performance uplift over previous generations for high-frame-rate gaming, heavy multi-tasking, and professional content creation.
Whether you are looking for the Intel Core i7-14700K Tray for custom liquid-cooled gaming builds or sourcing the Intel i7 14700K OEM CPU in volume for system integration, this unlocked processor provides peak clock speeds up to 5.6 GHz and full overclocking capability on LGA 1700 motherboards.
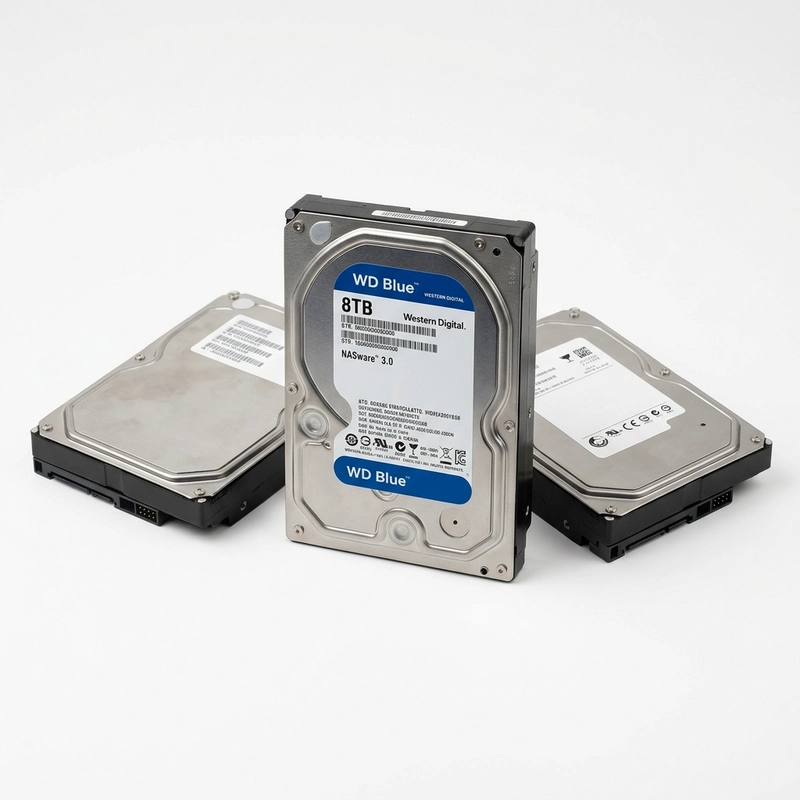
High-Capacity Mass Storage and Performance 8TB Hard Drives
Expand your storage capacity with the Western Digital HDD 8TB lineup and high-grade OEM hard drives. Designed for high-volume data needs, this 8TB storage series includes the everyday reliability of the WD Blue series as well as the high-speed performance of the WD Black 8TB.
Whether you need a fast mechanical disk for massive steam game libraries, a performance HDD for high-resolution video archives, or cost-effective OEM storage for wholesale desktop integration, these 3.5-inch hard drives deliver stable throughput, high durability, and low cost-per-gigabyte.
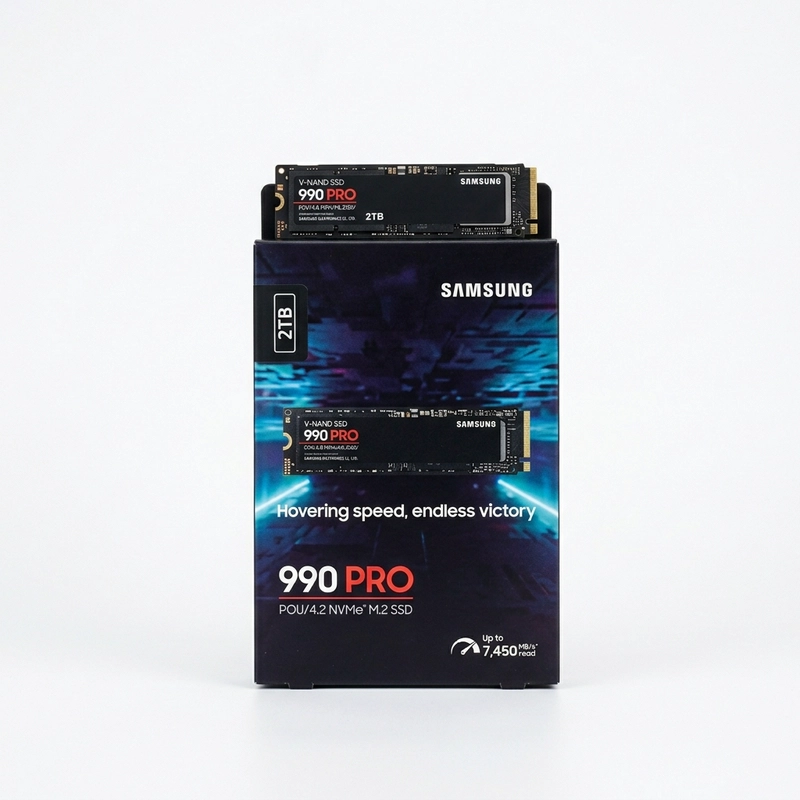
Experience Peak PCIe 4.0 Performance with the Samsung 990 PRO
Reach maximum PCIe 4.0 speeds with the Samsung 990 PRO, widely recognized as the best PCIe 4.0 SSD on the market today. Powered by Samsung's custom controller and advanced V-NAND technology, this drive delivers blazing-fast sequential read speeds of up to 7,450 MB/s, making it the ultimate choice for enthusiasts, competitive gamers, and professional creators seeking the fastest NVMe storage.
Whether you are rendering complex 3D projects, editing high-bitrate 4K/8K videos, or looking for a premium PS5 storage upgrade, the Samsung 990 PRO provides unrivaled speed, thermal control, and long-lasting endurance.
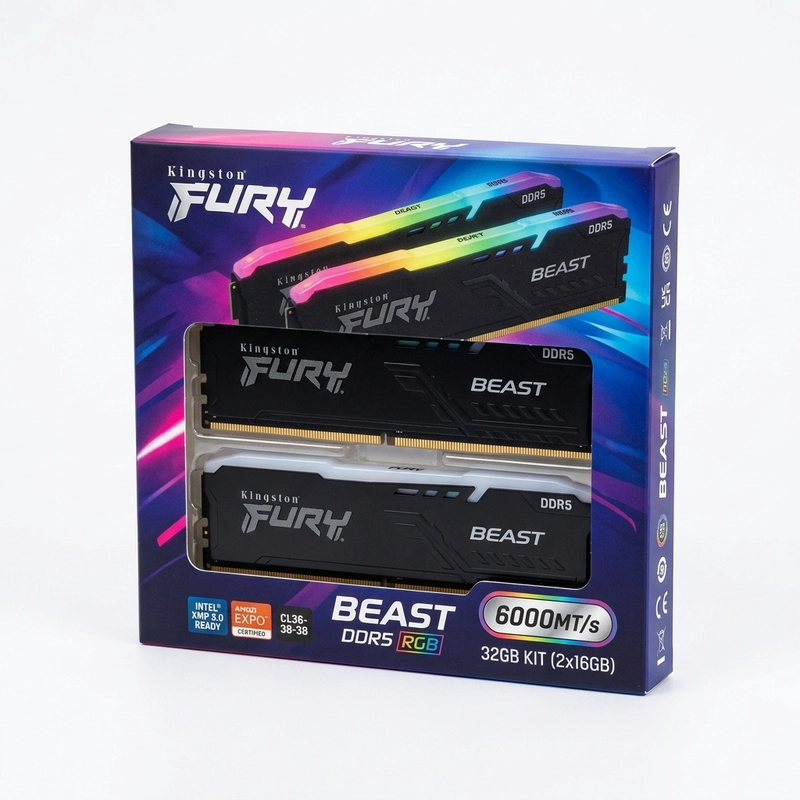
High-Speed 6000MHz Gaming Memory with Dynamic RGB Style
Unleash next-generation gaming performance with the Kingston FURY Beast RGB DDR5-6000. Engineered for hardcore gamers, overclockers, and system builders, this desktop RAM 6000MHz delivers extreme speeds and doubled bank architecture to give you the competitive edge in high-frame-rate gaming and intensive multitasking.
As a trusted leader in reliable DDR5 RAM, Kingston FURY Beast features customizable RGB lighting powered by Infrared Sync Technology, combined with Intel XMP 3.0 and AMD EXPO support for effortless plug-and-play overclocking.
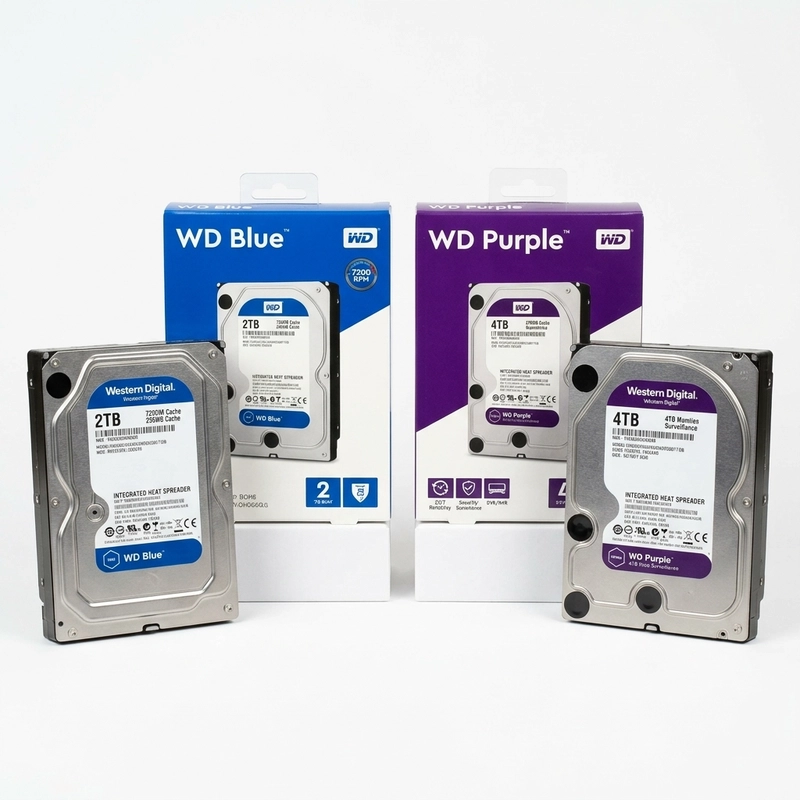
Reliable High-Capacity Enterprise HDDs and NAS Mass Storage Drives
Expand your storage infrastructure with our high-end NAS hard drives and enterprise HDDs. Engineered for continuous 24/7/365 operational availability, our mass storage drives deliver rock-solid reliability, massive data capacity, and low total cost of ownership (TCO) for data-intensive environments.
Whether you need bulk storage for multi-bay NAS enclosures, enterprise RAID arrays, cloud data centers, or customized OEM HDD deployments, our drives are optimized to ensure data integrity and peak operational efficiency under heavy sustained workloads.
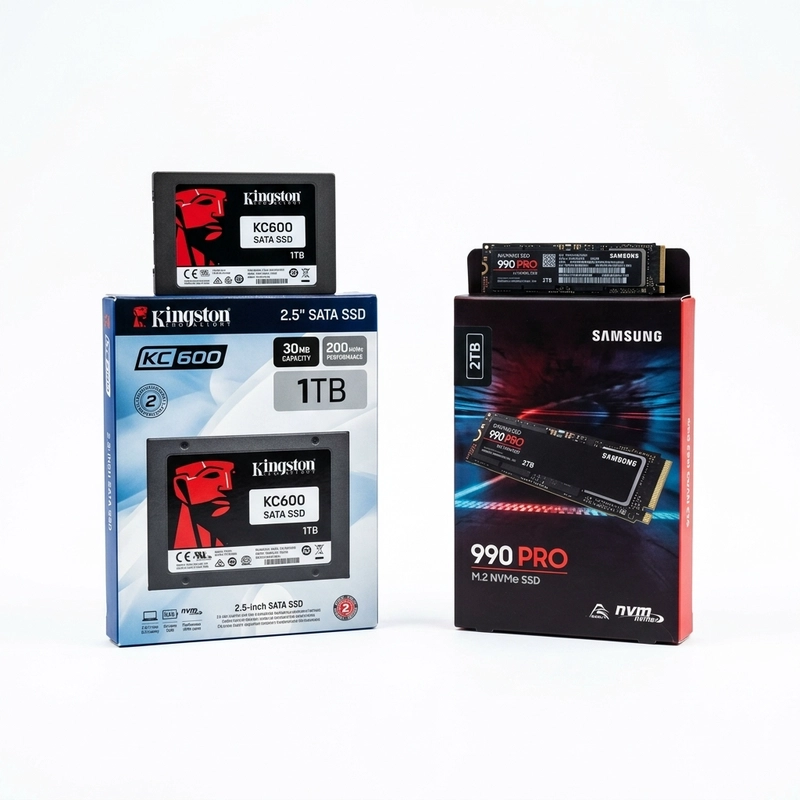
Ultra-Fast PCIe Gen4 & Gen5 NVMe M.2 Solid State Drives
Unlock extreme storage performance with our high-speed NVMe M.2 SSD series. Built with the latest PCIe SSD architecture, these drives deliver breathtaking read/write speeds, making them the ultimate upgrade for high-end gaming rigs, professional creative workstations, and data-intensive enterprise systems.
Featuring cutting-edge Gen4 and next-generation Gen5 technologies, our solid state drives ensure lightning-fast boot times, rapid application loading, and seamless transfer of massive files without throttling.
High-Performance Desktop, Notebook, and Server Memory Solutions
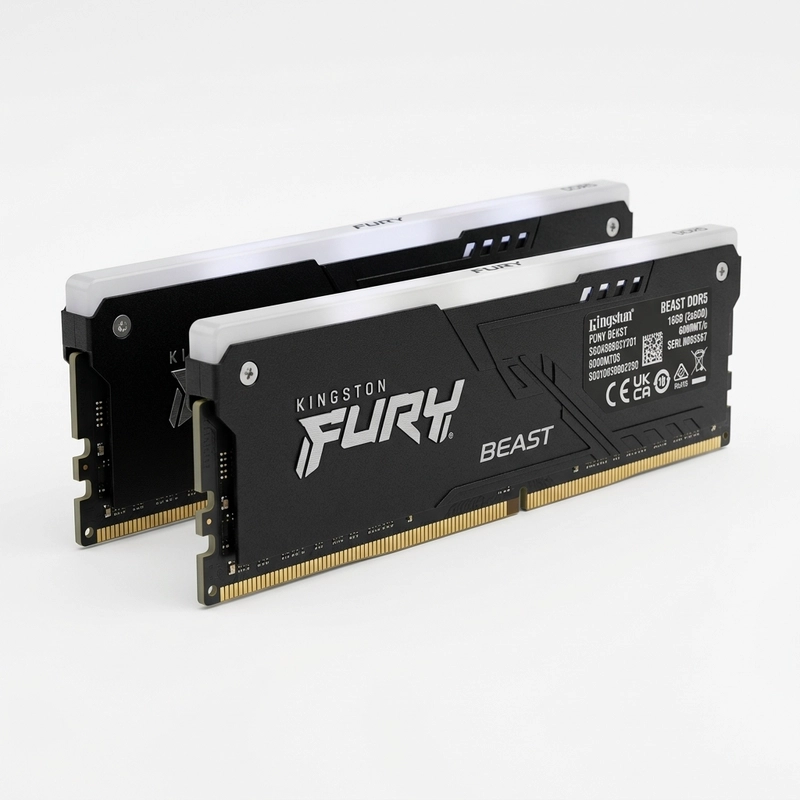
Upgrade your computing performance with our comprehensive line of DDR5/DDR4 RAM. Designed to meet the demanding requirements of individual builders, enterprise systems, and system integrators, our memory catalog covers high-speed Desktop memory, compact Notebook RAM, and rock-solid Server RAM.
We also specialize in OEM RAM manufacturing and supply, offering cost-effective, high-reliability memory modules tailored to wholesale distributors, PC assemblers, and IT infrastructure providers worldwide.
Power Your Workstations and Data Centers with Next-Gen Processors
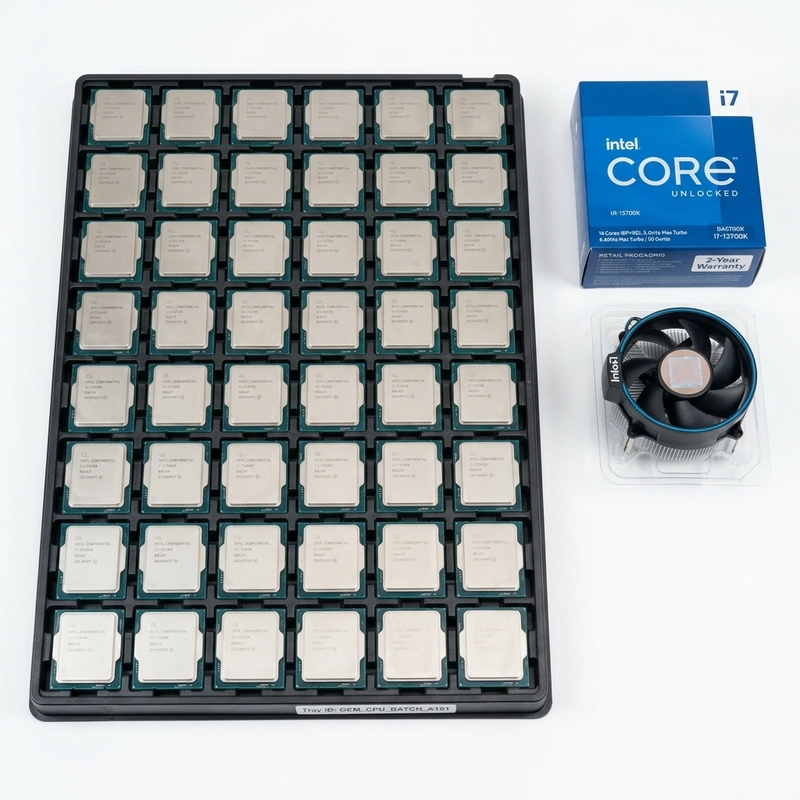
Discover our comprehensive selection of high-performance Desktop CPUs and Server CPUs, featuring cutting-edge Intel processors and AMD Ryzen processors. Whether you are building an extreme gaming rig, a professional creation workstation, or scaling up enterprise cloud infrastructure, our processors deliver unmatched computing power, high core counts, and exceptional energy efficiency.
Upgrade your hardware ecosystem with reliable, enterprise-grade processing technology designed to handle heavy multi-threading and intensive computational tasks.
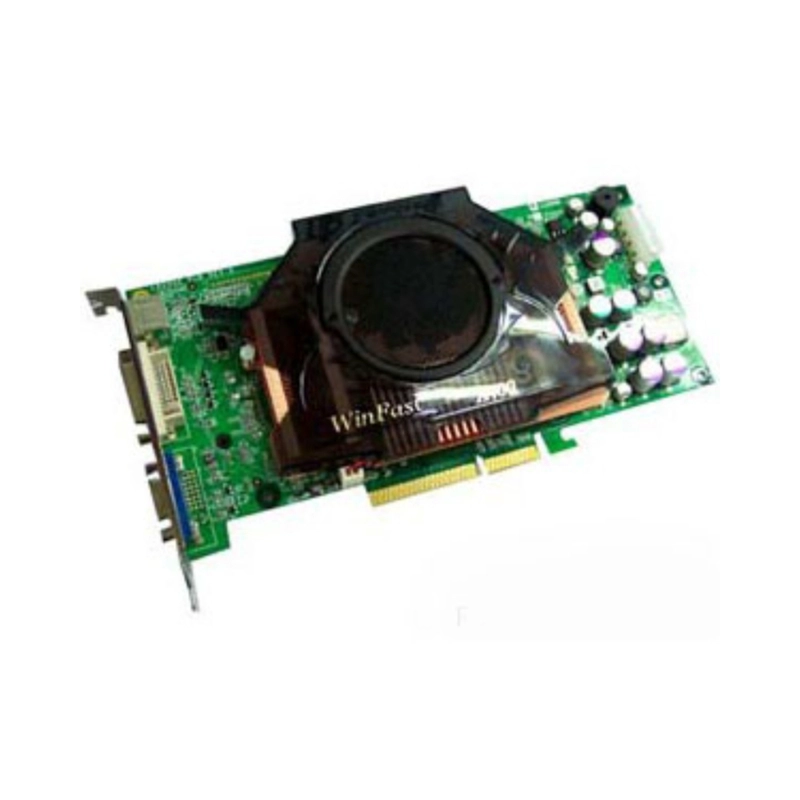
Leadtek NVIDIA Winfast A400LE TDH 128GB DDR Graphic Card